Posts Tagged ‘apachekafka’

How Flink’s Kafka connector commits offsets to Kafka

Saturday, October 24th, 2026

An unnecessarily deep dive into how Flink commits Kafka consumer offsets.

A pull request of mine was merged into flink-connector-kafka this week. A ridiculous number of sketches and diagrams went into the commits to get the idea straight in my head, so in this post I tidied them up a bit to share.

How consumer offsets are used by Flink

If you run a Flink job that reads from Kafka, you’ve probably seen its consumer group in your Kafka tooling like any other Kafka consumer: committed offsets for each partition, and a lag figure showing how far behind the log end the job is.

Flink doesn’t need to depend on those committed offsets for its own work. The unit of work for a Flink source is a “split”. For Kafka, a split is a partition and the offset to read from (and for a bounded split, the offset to stop reading at). This is stored in Flink state. Each source reader holds a split for every partition it reads, and each split records the next Kafka offset to read.

When Flink takes a checkpoint, each split is saved in the checkpoint, and contains those offsets. If the job fails, or you restart it from a savepoint, the source picks up from the offsets in the checkpoint. That’s how Flink can offer exactly-once processing: the offsets and the rest of the job’s state are captured together, in the same consistent snapshot.

Typically, the Kafka source reader commits the checkpointed offsets to Kafka once a checkpoint has completed. Although that is not necessary for the Flink job, it’s useful for lag dashboards and alerting, in the same way as any other Kafka consumer, and helps to understand how the job is doing.

Lag that wasn’t going away

FLINK-33484 reported a problem with a Flink job consuming a transactional topic with isolation.level=read_committed. The job had read everything on the topic, but the reported lag according to Kafka was stuck at 1, not 0.

A plain Kafka Java consumer reading the same data from the same topic reported no lag. Flink wasn’t committing the right offset.

Every time a record is handed on to the rest of the job, the split’s position was updated:

splitState.setCurrentOffset(consumerRecord.offset() + 1);

The next offset to read is the one after the last record.

That’s the right thing to do for a non-transactional, uncompacted topic, where every offset holds a record.
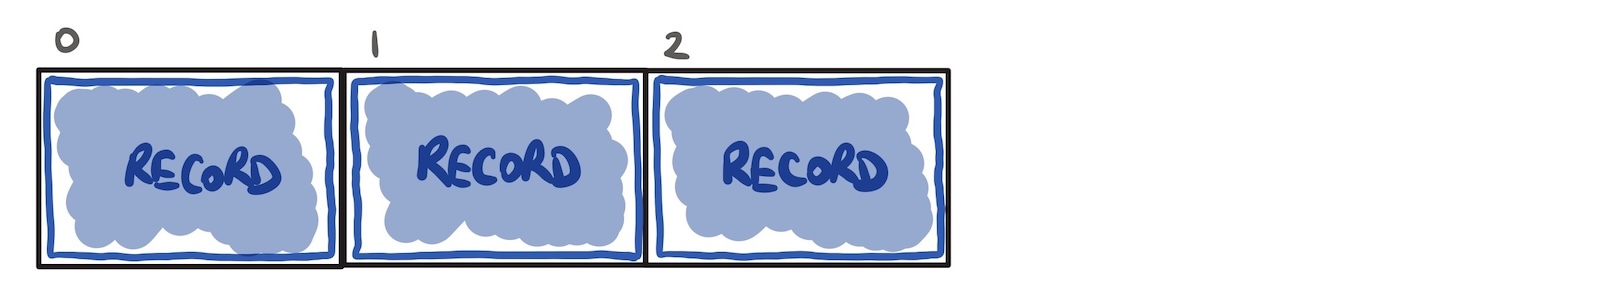
It’s not always the right thing to do.

When a Kafka producer commits or aborts a transaction, the broker writes a transaction marker into each partition the transaction touched. That marker takes up an offset in the log like any other entry.
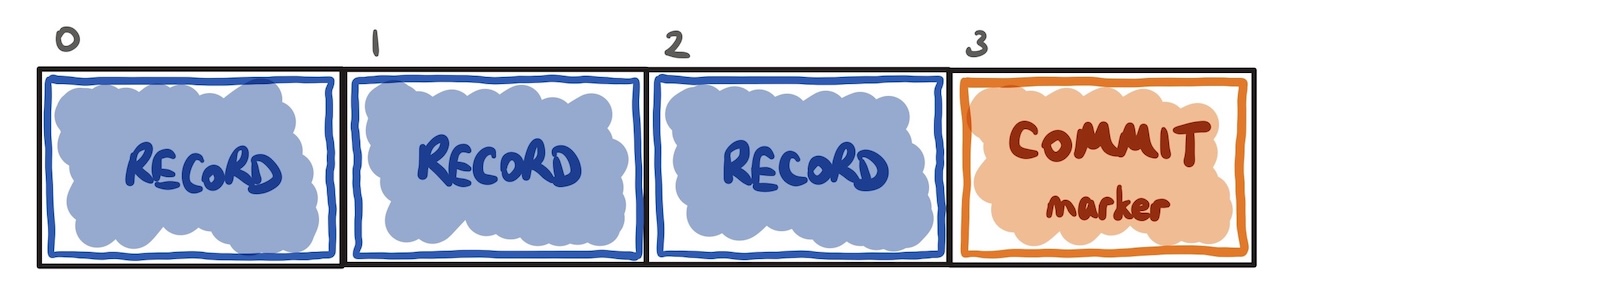
This is handled by the Kafka consumer. Transaction markers aren’t given to the application.

And if the application only asks for committed records (read_committed), records from aborted transactions are skipped in the same way. The consumer reads past them, and its position moves forward, but no record comes out for them.

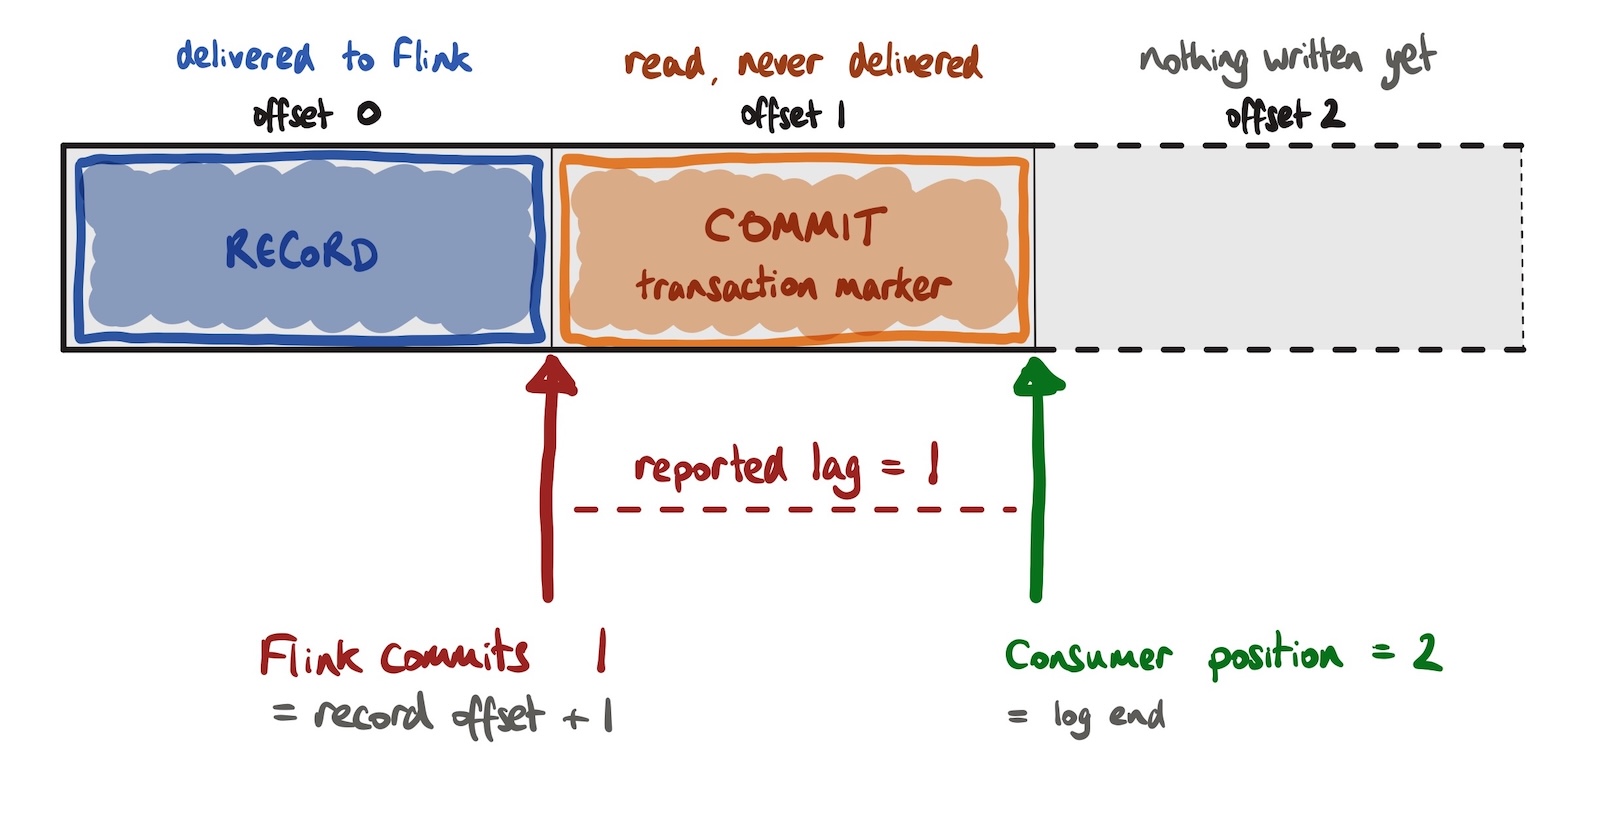
Imagine a Kafka producer writes a single record in a transaction and commits it:

offset 0 record delivered to Flink
offset 1 commit marker read by the consumer
not delivered to Flink

The topic partition’s log end offset (and last stable offset) is 2 because that’s where the next entry will be written.

Flink emitted the record at offset 0, and set the split’s current offset to 1 (because it added 1 to the offset it’s emitted).

The Kafka consumer has actually read past the transaction marker, so its position is 2.

But at the next checkpoint, Flink committed an offset of 1.

Any Kafka tooling set up to monitor Kafka consumer progress compared that with a log end of 2, and reported a lag of 1.
On a busy topic, you’d barely notice. The next record arrives, gets emitted, and the committed offset jumps over the marker. The committed offset was always slightly behind, but only until new data arrives.

On a quiet or bursty topic, “until new data arrives” can be a long time. The job was fully caught up, but every checkpoint committed the same stale offset, and Kafka monitoring reported a lag that didn’t exist.

That was FLINK-33484 that I picked up a little while ago.
(more…)

Presenting at Current / Kafka Summit

Thursday, May 21st, 2026

A few of us at Current this week were talking about how Current (formerly “Kafka Summit”) has changed over the years, and it got me remembering the bits I’ve contributed.

I dug through some old posts to find seven Current / Kafka Summit talks I’ve done… it makes for an eclectic set when I see it in one list!

Embedding Tiny Language Models in Flink SQL

Wednesday, May 20th, 2026

I gave a talk at Current yesterday about how to embed a tiny language model inside your Flink SQL pipeline.

I used a fun mix of demos to show what I think are the main approaches available for using generative AI with Kafka events from a Flink SQL job. Some demos were definitely more sensible than others!

These are the slides I used, and what I’d planned to say.

#

In this session, I’ll be talking about your options for running language models for Flink SQL jobs.

I’ll cover:

  • your options for where you run them, in relation to Flink
  • what sorts of choices you have for the models you run
  • how to use them – the sorts of prompts and settings we’d want for Flink
  • how to keep an eye on it that it’s working well
  • and finally, some thoughts on when it’s a good idea to do any of this

(more…)

Instrumenting a Kafka Connect connector with metrics

Saturday, May 2nd, 2026

Metrics can help provide operational insight over Kafka Connect connectors, informing users of how to better configure them. With simple updates, a Kafka Connect connector can be instrumented to make this possible by emitting useful metrics.

A couple years ago, I created a simple skeleton Connect connector project to help developers at a hackathon create their first Kafka connector.

I’ve updated the source connector from that sample to emit metrics. In this post, I’ll walk through what I did, as an example for how to add metrics to your own Kafka connector.

(more…)

Talking at TechCon about metrics and monitoring

Saturday, March 21st, 2026

IBM TechCon is an annual online technical event for engineers, creators, and integration specialists.

One of our sessions for this year was an introduction to Monitoring your Event Driven Architecture:

This session will give you an insight into the life of an Event Automation administrator, responsible for a busy event-driven system where teams have been creating a variety of Kafka topics, integrations, stream processing apps, connectors, and much more. We’ll highlight the importance of metrics and monitoring for event driven architectures and introduce you to the tools that are available to help.

We’ll do this by showing you an event-driven environment where things have gotten out of hand. In our fictional scenario, users are being impacted by things like poorly configured topics, poorly written applications, poorly managed connectors, poorly configured stream processors…

In this session, we’ll walk you through to bring control to the chaos. We’ll step through how to get an insight into what is happening, find out where the problems are, and put controls in place to mitigate their impact.


session recording on video.ibm.com

It was an introduction for beginners, that you could sum up as a 40-minute plea for people to monitor their Kafka clusters and applications! Essentially, we set up a handful of naive and broken applications, and walked through how metrics and monitoring show you where the problems are hiding.

Watch it to be persuaded that metrics are important.

Or to watch how Matt had to jump in and help me when an Apple Magic Mouse decide it didn’t like scrolling any more, and I needed to get to things at the bottom of web pages!

Or just to marvel at how glamourous our offices are. 😉

Processing JSON with Kafka Connect

Wednesday, February 18th, 2026

In this post, I’ll share examples of how to process JSON data in a Kafka Connect pipeline, and explain the schema format that Kafka uses to describe JSON events. 

Using sink connectors

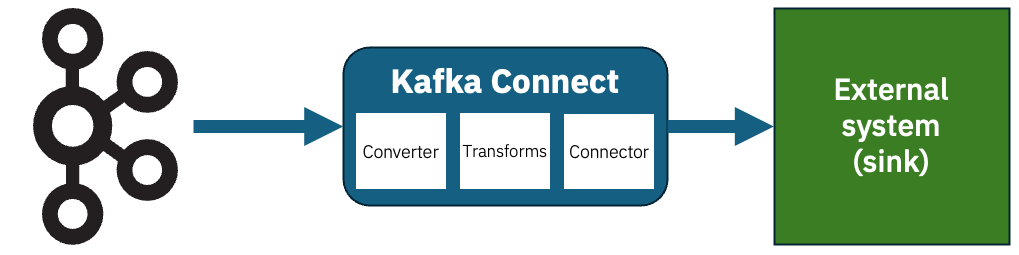
Kafka Connect sink connectors let you send the events on your Kafka topics to external systems. I’ve talked about this before, but to recap the structure looks a bit like this:

Imagine that you have this JSON event on a Kafka topic. 

{
    "id": 12345678,
    "message": "Hello World",
    "isDemo": true
}

How should you configure Kafka Connect to send that somewhere? 

It depends…

(more…)

AI patterns in event driven architectures

Monday, November 3rd, 2025

I gave a talk at Current last week about how artificial intelligence and machine learning are used with Kafka topics. I had a lot of examples to share, so I wrote up my slides across several posts.

I’ll use this post to recap and link to my write-ups of each bit of the talk:

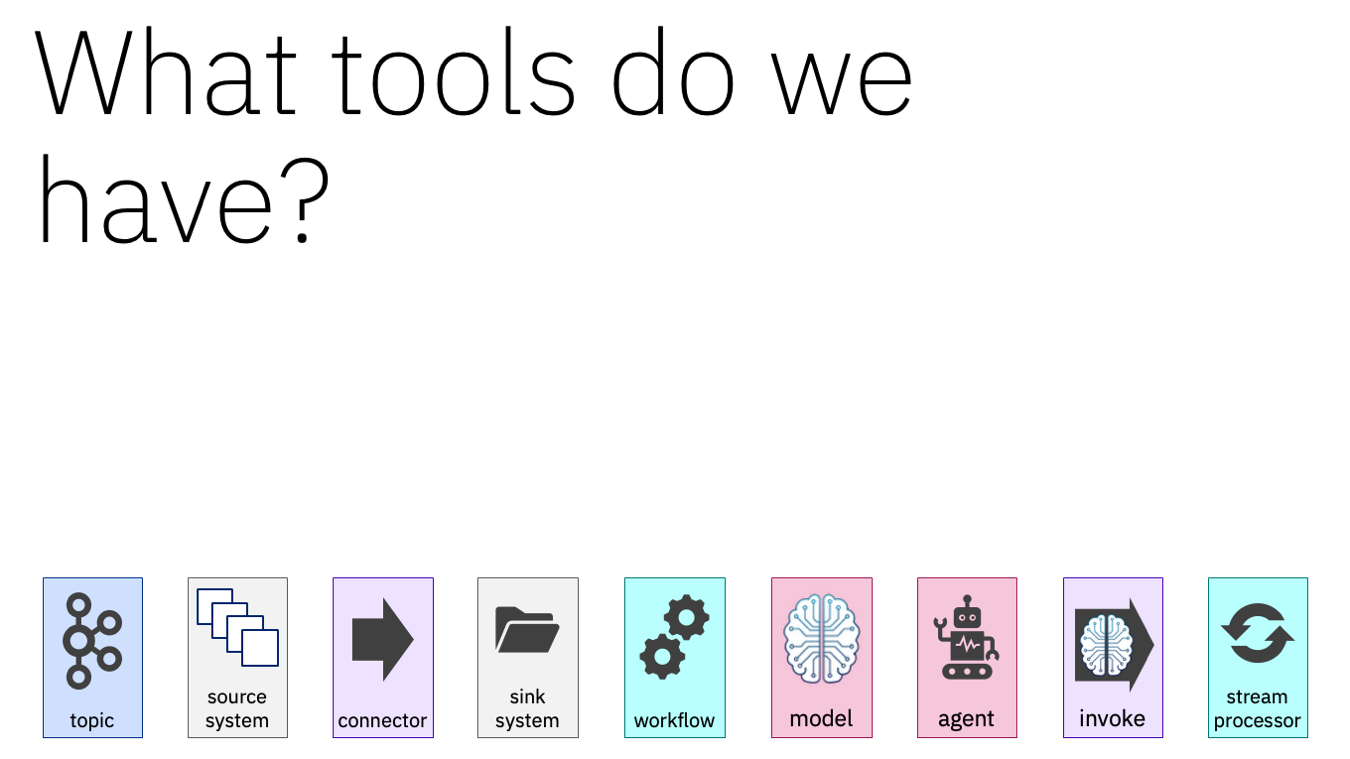
I started by talking about the different building blocks that are needed, and the sorts of choices that teams make.

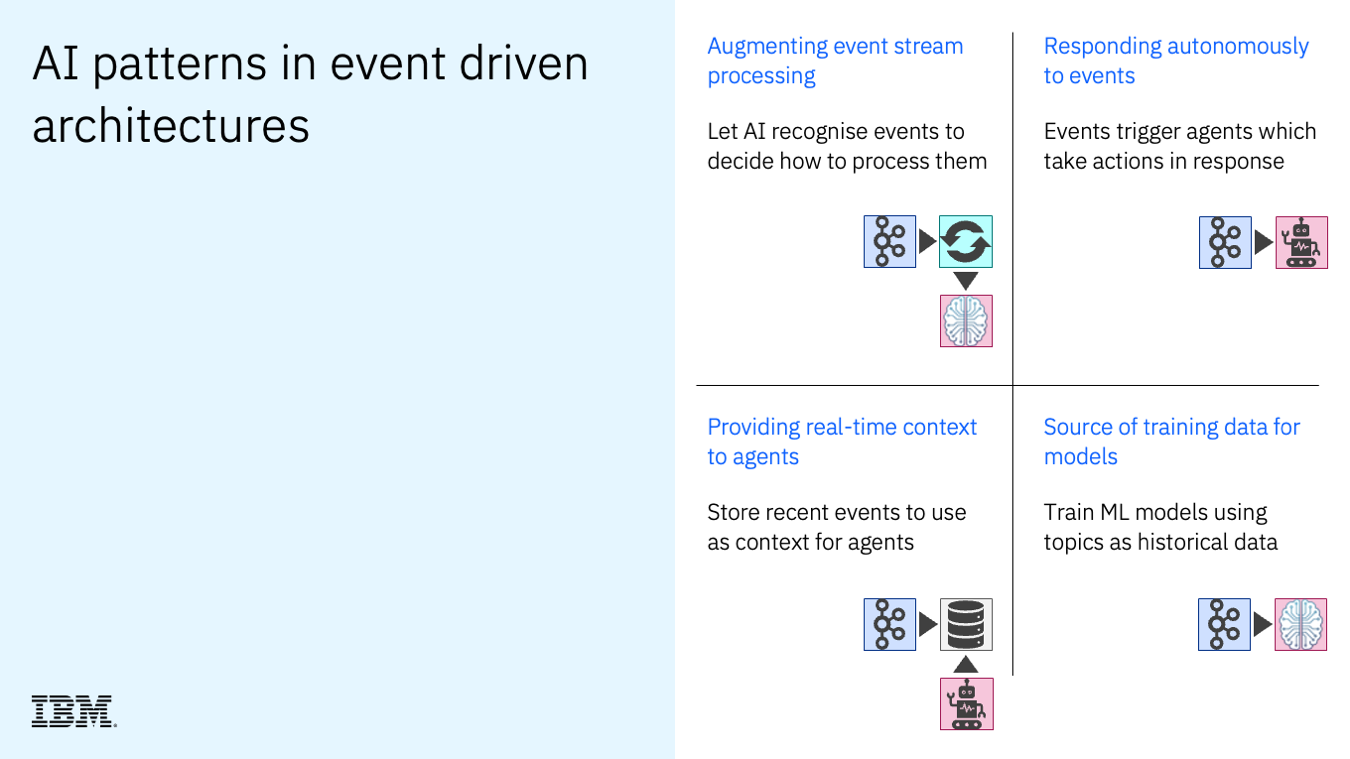
Next, I talked about how projects to introduce AI into event driven architectures typically fall into one or more of these common patterns:

The most common, and the simplest: using AI to improve and augment the sorts of processing we can do with events. This can be as simple as using off-the-shelf pre-trained models to enrich a stream of events, and using this to filter or route the event as part of processing.

Perhaps the newest (and the pattern that is recently getting the most interest and attention) is to use streams of events to trigger agents, so that they can autonomously take actions in repsonse.

Maybe the less obvious approach is to collect and store a projection of recent events, and use these to enhance an agentic AI, by making it available as a queryable or searchable form of real-time context.

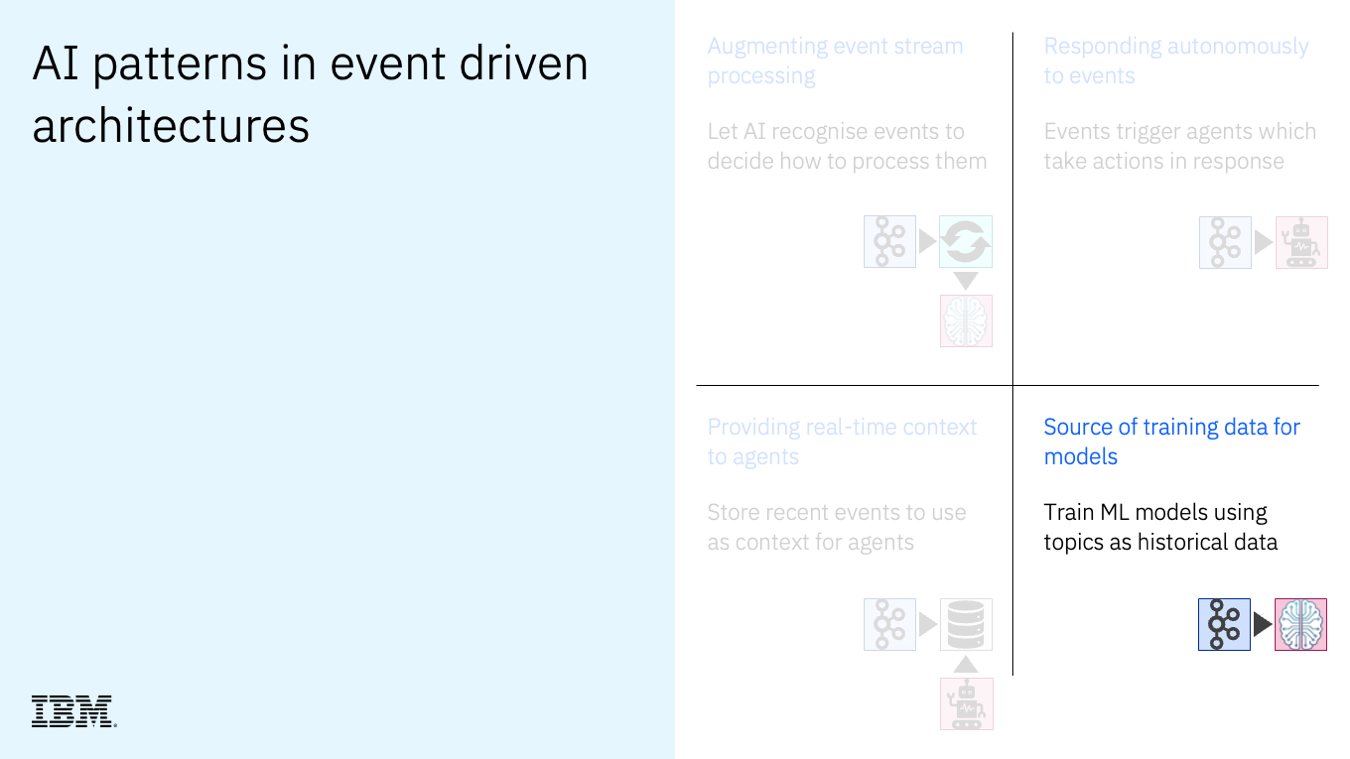
And finally, the longest established pattern is to simply use the retained history of Kafka topics as a relevant source of historical training data, for training new custom and bespoke models.

Using streams of events to train machine learning models

Sunday, November 2nd, 2025

In this post, I describe how event streams can be used as a source of training data for machine learning models.

I spoke at Current last week. I gave a talk about how artificial intelligence and machine learning are most commonly used with Kafka topics. I had a lot to say, so I didn’t manage to finish writing up my slides – but this post covers the last section of the talk.

It follows:

The talk covered the four main patterns for using AI/ML with events.

This pattern was where I talked about using events as a source of training data for models. This is perhaps the simplest and longest established approach – I’ve been writing about this for years, long pre-dating the current generative AI-inspired interest.

(more…)