Posts Tagged ‘flink’

How Flink’s Kafka connector commits offsets to Kafka

Saturday, October 24th, 2026

An unnecessarily deep dive into how Flink commits Kafka consumer offsets.

A pull request of mine was merged into this week. A ridiculous number of sketches and diagrams went into the commits to get the idea straight in my head, so in this post I tidied them up a bit to share.

How consumer offsets are used by Flink

If you run a Flink job that reads from Kafka, you’ve probably seen its consumer group in your Kafka tooling like any other Kafka consumer: committed offsets for each partition, and a lag figure showing how far behind the log end the job is.

Flink doesn’t need to depend on those committed offsets for its own work. The unit of work for a Flink source is a “split”. For Kafka, a split is a partition and the offset to read from (and for a bounded split, the offset to stop reading at). This is stored in Flink state. Each source reader holds a split for every partition it reads, and each split records the next Kafka offset to read.

When Flink takes a checkpoint, each split is saved in the checkpoint, and contains those offsets. If the job fails, or you restart it from a savepoint, the source picks up from the offsets in the checkpoint. That’s how Flink can offer exactly-once processing: the offsets and the rest of the job’s state are captured together, in the same consistent snapshot.

Typically, the Kafka source reader commits the checkpointed offsets to Kafka once a checkpoint has completed. Although that is not necessary for the Flink job, it’s useful for lag dashboards and alerting, in the same way as any other Kafka consumer, and helps to understand how the job is doing.

Lag that wasn’t going away

FLINK-33484 reported a problem with a Flink job consuming a transactional topic with isolation.level=read_committed. The job had read everything on the topic, but the reported lag according to Kafka was stuck at 1, not 0.

A plain Kafka Java consumer reading the same data from the same topic reported no lag. Flink wasn’t committing the right offset.

Every time a record is handed on to the rest of the job, the split’s position was updated:

splitState.setCurrentOffset(consumerRecord.offset() + 1);

The next offset to read is the one after the last record.

That’s the right thing to do for a non-transactional, uncompacted topic, where every offset holds a record.
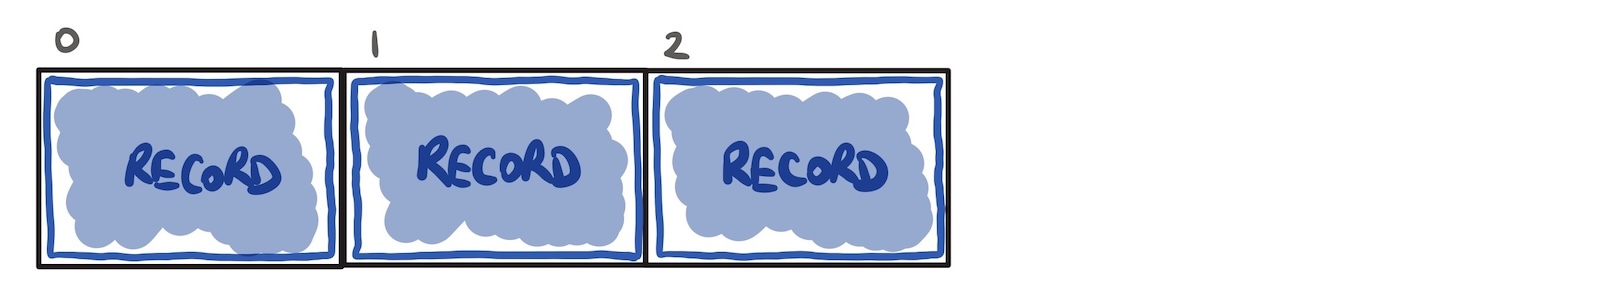
It’s not always the right thing to do.

When a Kafka producer commits or aborts a transaction, the broker writes a transaction marker into each partition the transaction touched. That marker takes up an offset in the log like any other entry.
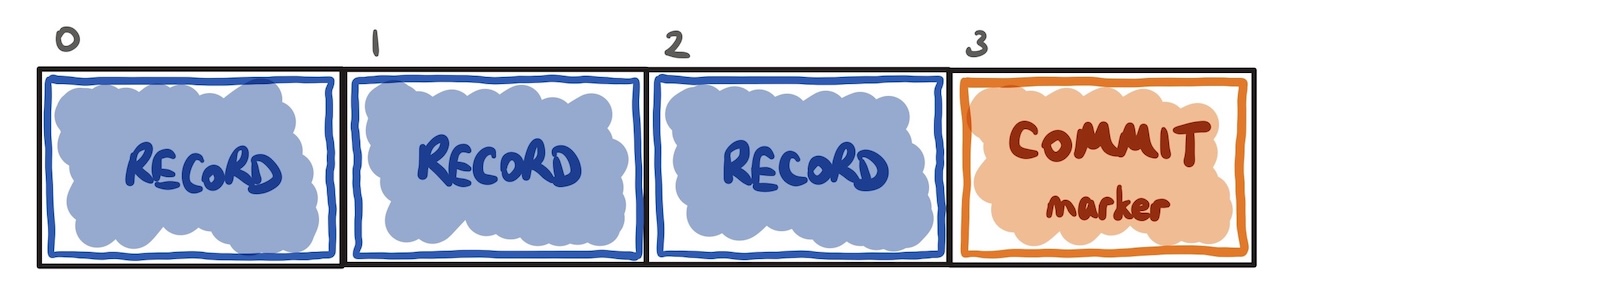
This is handled by the Kafka consumer. Transaction markers aren’t given to the application.

And if the application only asks for committed records (read_committed), records from aborted transactions are skipped in the same way. The consumer reads past them, and its position moves forward, but no record comes out for them.

Imagine a Kafka producer writes a single record in a transaction and commits it:

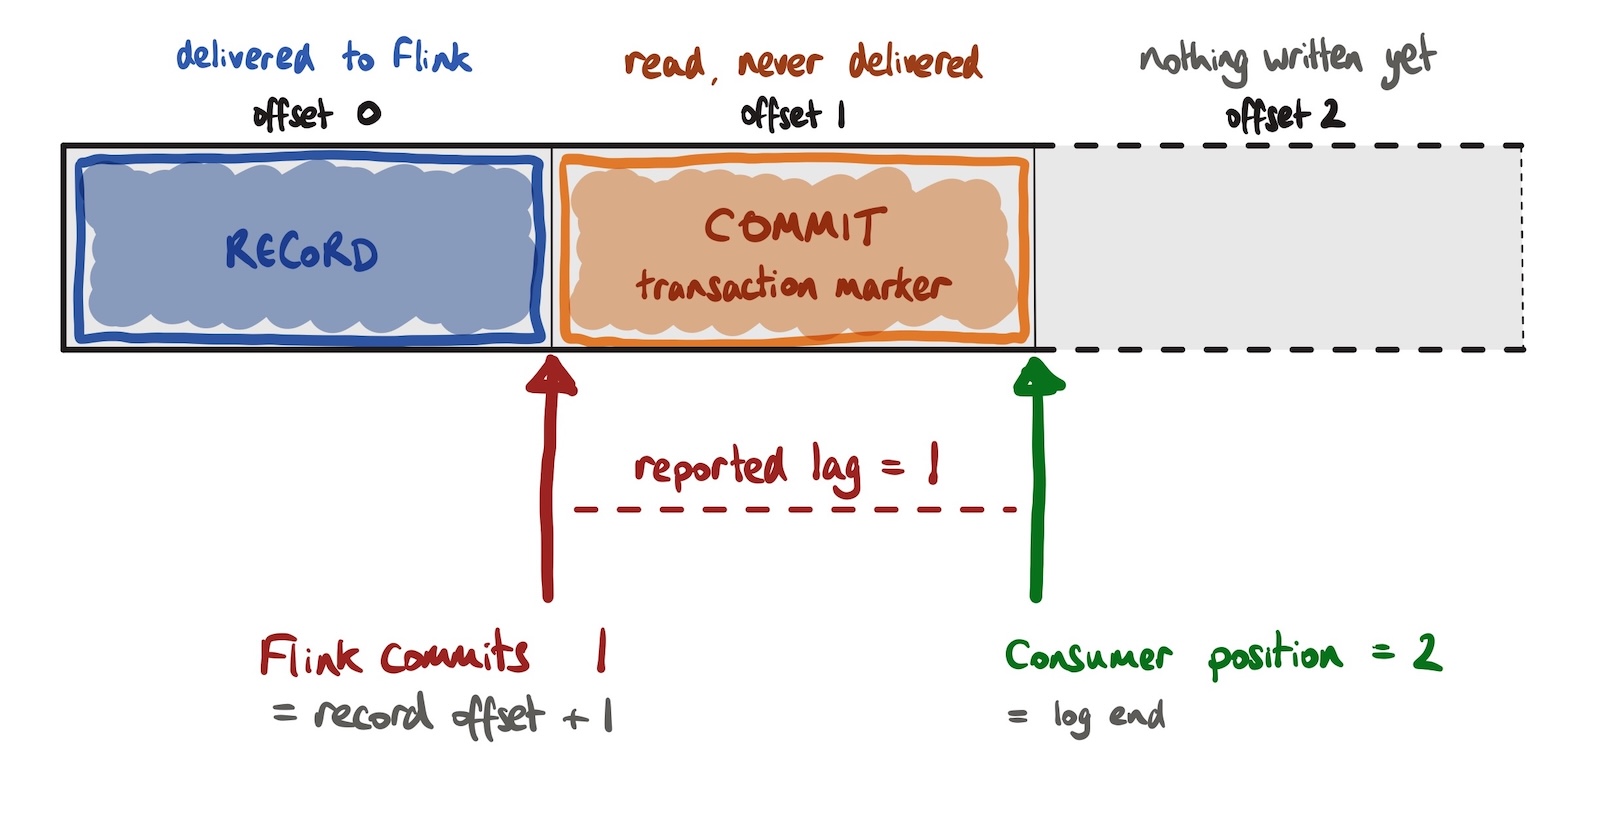
offset 0 record delivered to Flink
offset 1 commit marker read by the consumer
not delivered to Flink

The topic partition’s log end offset (and last stable offset) is 2 because that’s where the next entry will be written.

Flink emitted the record at offset 0, and set the split’s current offset to 1 (because it added 1 to the offset it’s emitted).

The Kafka consumer has actually read past the transaction marker, so its position is 2.

But at the next checkpoint, Flink committed an offset of 1.

Any Kafka tooling set up to monitor Kafka consumer progress compared that with a log end of 2, and reported a lag of 1.
On a busy topic, you’d barely notice. The next record arrives, gets emitted, and the committed offset jumps over the marker. The committed offset was always slightly behind, but only until new data arrives.

On a quiet or bursty topic, “until new data arrives” can be a long time. The job was fully caught up, but every checkpoint committed the same stale offset, and Kafka monitoring reported a lag that didn’t exist.

That was FLINK-33484 that I picked up a little while ago.
(more…)

Adding support for remote jar fetching in Flink session clusters

Sunday, August 23rd, 2026

I’ve submitted a Flink Improvement Proposal (FLIP) about adding support for Flink to be able to fetch remote jars for applications submitted to a session cluster.

Discussion thread on lists.apache.org

(more…)

Running Flink jobs in MiniCluster using the Kubernetes Operator

Wednesday, August 5th, 2026

I’ve submitted a Flink Improvement Proposal (FLIP) about adding support for the Flink Kubernetes Operator to run Flink’s MiniCluster in a single pod for low-throughput jobs that require isolation.

In the last few weeks, I’ve been working on a proof-of-concept to demonstrate the feasibility of this idea. I’ve done enough to convince myself that this is viable and identify where the issues will be, but I’m looking for community feedback before I take it much further.

Background

The Flink Kubernetes Operator is one of the best ways to run Flink jobs. From the documentation:

Flink deployments are declared like any other Kubernetes workload, and the operator runs their whole operational life:

  • Lifecycle Management: deployment, stateful upgrades, rollbacks, and self-healing
  • Zero-Downtime Upgrades: blue/green deployments that switch over only once the new version is proven healthy
  • Autoscaling: parallelism and memory continuously right-sized to the observed load
  • Kubernetes-Native Operations: Helm installation, RBAC, high availability, metrics, logging, and ingress

You create a FlinkDeployment Kubernetes custom resource that points to your Flink application, and the Operator handles provisioning independently schedulable and independently configurable Job Manager Deployment and Task Manager Deployment, configuring them to form a distributed Flink cluster.

This provides scalability and high availability, and is the right approach in a lot of situations. However, this comes at the cost of a fixed baseline cost of at least one JobManager pod and one or more TaskManager pods.

A smaller, lighter-weight alternative would be useful for small or intermittent jobs, where the minimum resource cost of two separately-scheduled pods is disproportionate to the job itself.

A single-pod, self-contained Flink job that starts fast and needs no multi-pod coordination could be a good fit for low-throughput jobs that aren’t suitable for session clusters because they need isolation.

(more…)

Embedding Tiny Language Models in Flink SQL

Wednesday, May 20th, 2026

I gave a talk at Current yesterday about how to embed a tiny language model inside your Flink SQL pipeline.

I used a fun mix of demos to show what I think are the main approaches available for using generative AI with Kafka events from a Flink SQL job. Some demos were definitely more sensible than others!

These are the slides I used, and what I’d planned to say.

#

In this session, I’ll be talking about your options for running language models for Flink SQL jobs.

I’ll cover:

  • your options for where you run them, in relation to Flink
  • what sorts of choices you have for the models you run
  • how to use them – the sorts of prompts and settings we’d want for Flink
  • how to keep an eye on it that it’s working well
  • and finally, some thoughts on when it’s a good idea to do any of this

(more…)

“How many Kafka events will Flink process per second?”

Saturday, April 11th, 2026

I’m often asked this. The specific question varies, but it’s typically some variation of asking how quickly a single CPU of Flink processes events from a Kafka topic.

Why “per CPU”? Maybe because enterprise software is typically charged per CPU? Maybe because I tend to talk to people who run everything in Kubernetes, who think of running software in terms of requests / limits? Not sure, but the question tends to be framed from the perspective of asking how much processing they can expect to get from a CPU.

I try to avoid doing the engineer thing of answering “it depends“… but… it really does depend!

That is the motivation behind this post: to give me something I can point at as an illustration of the degree to which Flink’s performance varies (and a taste of the range of interrelated factors that influence it).

(more…)

Extending Flink SQL

Sunday, March 29th, 2026

In this post, I’ll share examples of how writing user-defined functions (UDFs) extends what is possible using built-in Flink SQL functions alone.

I’ll share examples of how UDFs can:

(more…)

Deploying Apache Flink jobs into Kubernetes

Friday, March 20th, 2026

IBM TechCon is an annual online technical event for engineers, creators, and integration specialists.

One of our sessions for this year was Deploying an Apache Flink job into production:

You’ve maybe seen the low-code canvas in Event Processing or the simple expressiveness of Flink SQL, and how easy they make it to author event stream processing. A business user who understands the data in the event stream can easily describe the patterns they’re interested in or the insights they want to look for. But what comes next?

In this session, we’ll walk through the ops tasks involved in taking that event processing flow, and deploying it into Kubernetes as a Flink application ready for production.

We’ll outline the steps that are needed and describe the main decisions you need to make. This includes the sorts of values you will want to monitor to make sure that your Flink application continues to run correctly.


session recording on YouTube

It was a live walk-through of the steps involved in deploying Flink jobs in Kubernetes. I used Event Processing to create the Flink job that I used for the demos, because low-code UI’s are easier to follow in a presentation, but most of what I showed is applicable however you’ve created your Flink job – and was a high-level introduction to using the Flink Kubernetes Operator.

Flink SQL examples with click tracking events

Monday, January 12th, 2026

In this post, I introduce a few core Flink SQL functions using worked examples of processing a stream of click tracking events from a retail website.

I find that a practical, real-world (ish) example can help to explain how to use Flink SQL in a way that abstract descriptions, such as processing coloured blocks sometimes doesn’t quite achieve.

I’ll use this post to give examples of my most-used Flink SQL functions, in the context of a retail scenario: a stream of events from customers on the website for a clothing retailer.

Note: I used Event Processing to create the flows, as the assistants in the canvas helped me create examples quickly. Everything I’ve created is standard Apache Flink SQL, so you don’t need to have Event Processing to try these examples.

(more…)